Quantumania 23 - Turn! Turn! Turn!
The reflections  ,
 ,
 were figured out by Pauli, who started with some basic constraints imposed by what was already known in 1927 (a pretty important year in QM.) First, it was known since 1922’s Stern-Gerlach experiment that if you put a beam of silver atoms through a linear magnetic gradient, they behave as if every atom is a little bar magnet (a unit of magnetic moment) that is aligned exactly with the gradient, one way or the other. Half of them go up, half go down, the beam is split so makes two bright dots on the screen. This was surprising because you’d assume from classical intuition that they would fan out, each atom having a random orientation relative to the gradient.
Second, Dirac had already explained that in QM, if a quantum system has a measurable property with two possible outcomes, the vector state space for that system is two dimensional. Putting these first two concepts together, the state space describing the orientation of a particle’s magnetic moment must be two dimensional.
Third, by feeding the “up” output particle beam from the above experiment into exactly the same kind of apparatus, but with the magnetic gradient rotated  , the beam splits again, left/right. This makes sense if you think of each particle’s magnetic moment as a dot on a sphere, and each of these stages acting as a filter that only allows through particles whose dot is in one of the two hemispheres, divided by an equator that depends on the alignment of the magnetic gradient. If the particles’s dots are randomly distributed over the sphere of possible spatial directions, only half of them have their dot in the upper hemisphere, and then of that beam, only half qualify as right hemisphere, and so on. The second stage’s rightward beam must, you’d naively think, therefore contain only particles whose dot is in the upper-right quarter (they’ve made it through both filters.)
And so a third stage aligned to split up/down again should only produce a single up beam. But it produces two equal beams, up and down. From this we are forced to conclude that each stage, when treated as a filter, has the effect of snapping every particle into alignment with its field gradient, one way or the other, and that therefore the second stage wipes out the alignments produced by the first stage. Also there seems to be a random choice made for each particle as to which way to snap into alignment.
Again, Dirac had already established the rules of QM here: the two dimensional (complex) state space for particle alignment has to represent mutually exclusive measurement outcomes, such as up/down, with orthogonal vectors, and other (incompatible) observable outcomes, such as left/right, must be expressible as a sum of up/down, and vice versa. Also observables correspond to self-adjoint operators (Hermitian matrices). With these rules in place, and the results of Stern-Gerlach, Pauli found that there was exactly one way to arrange the state vectors for three orthogonal spatial directions, and the operators for the observables corresponding to those directions are the three reflections around  ,
 and
 , which are , and respectively.
Now, the first thing to notice about Pauli’s three matrices is that they are traceless. This means that the sum of their eigenvalues is zero, as they are QM operators, thus self-adjoint, thus normal, which is to say amenable to being diagonalised, in which form they are all just  . They can be linearly combined to represent any alignment in space, to make Hamiltonians (energy operators) that steer the evolution of a particle’s spin orientation.
But any such combination will also have zero trace (the trace is a linear operator, so the trace of a sum of matrices is the sum of their individual traces). Therefore we can’t make any old matrix with these three ingredients, only those that possess this particular quality of balanced eigenvalues on either side of zero. We can’t make a matrix with eigenvalues  , for example. This inability of three matrices to span the space of all possible
 matrices is hardly surprising: it’s clearly a 4-dimensional space, so we need a forth ingredient, one that acts as a kind of “unit of trace”, a constant to be added to all the diagonal entries to offset their total away from zero. This ingredient is simply
 . But physically the significance of energy levels is the difference between them, so we don’t usually require this ingredient to model an actual Hamiltonian. Balancing the energy levels around zero is neat and symmetrical. It’s just interesting to note that is theoretically one of the four ingredients alongside , and , even if our interest in its involvement falls away rapidly when we realise what its role would be.
But there is another role for in combination with the other Pauli matrices. Recall how every state has a second way of being represented, as a density matrix. This means that every point on the Bloch sphere, being a definite state, corresponds to a density matrix. The rules for density matrices are:
- They must be Hermitian, so their eigenvalues are real, because they are probabilities.
- The eigenvalues must also be non-negative, for the same reason.
- If diagonalised (as they always can be in some basis) their eigenvalues appear on the diagonal, and being an exhaustive set of probabilities, they must sum to
 , which is to say that the trace must be .
Now, by a weighted sum of the three Pauli matrices , , , each having their own real weighting coefficient  ,
 ,
 , we are able to make a matrix corresponding any point on the Bloch sphere:
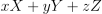
The real coordinates  specify a point anywhere in 3D space, but we want to only target the surface of the unit sphere, so we require
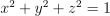 . But as noted, the trace of any such combination will be 0, as the eigenvalues will always be and
 . So it’s not yet a valid density matrix. But this is where comes to the rescue!
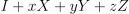
We’ve added a unit of “positive trace” to the diagonal, so now the eigenvalues are  . So close! We need to scale them down to
 :
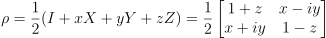
The second thing to notice is that while , and act as reflections in the state space, this is not what they do on the Bloch sphere. As always, this is an area ripe for confusion. Recall that flips the sign on  only:

On the Bloch sphere, these two vectors are the up/down poles, and of course a sign flip doesn’t move anything. So on the sphere, has no effect at all on these two states. They stay put. What happens to and  , which sit on the front/back poles? They actually switch places:
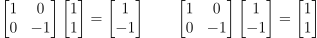
Exactly the same thing happens with and  , unsurprisingly. So this is in fact a
 rotation around the -axis. Each matrix, while being a simple reflection in state space, is a rotation in physical space. But because it’s a rotation, applying it twice in succession will restore the starting state, which is consistent with a reflection in state space. By constructing a linear combination of the three we can make a rotational axis in any direction we require.
The third thing to notice is what happens when you multiply the three directional matrices together in certain pairs with ordinary matrix multiplication:
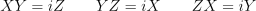
Seemingly any pair is a way to make the remaining one, well, almost, apart from that  factor. Though if you flip the order, it introduces a minus sign:
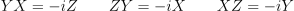
And here is an interesting thing. Define the following mystery objects:

That is, each is just a Pauli matrix multiplied by  . For completeness we’ll give a new symbol to the identity operator:

What happens when we square them? It’s just matrix multiplication, and we know the Pauli matrices are self-inverse:
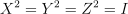
So the extra factor produces :
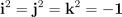
And if you multiply pairs of them, the extra factor preserves itself:
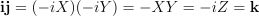
Or to tabulate all pairings systematically:
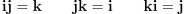
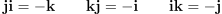
and for good measure (by simple substitution from the above discoveries):

The curious thing is that if you start from a very simple premise, you can derive these rules and they work exactly like the Pauli matrices.
Not yet regretting the time you've spent here?
Keep reading: